Agriculture
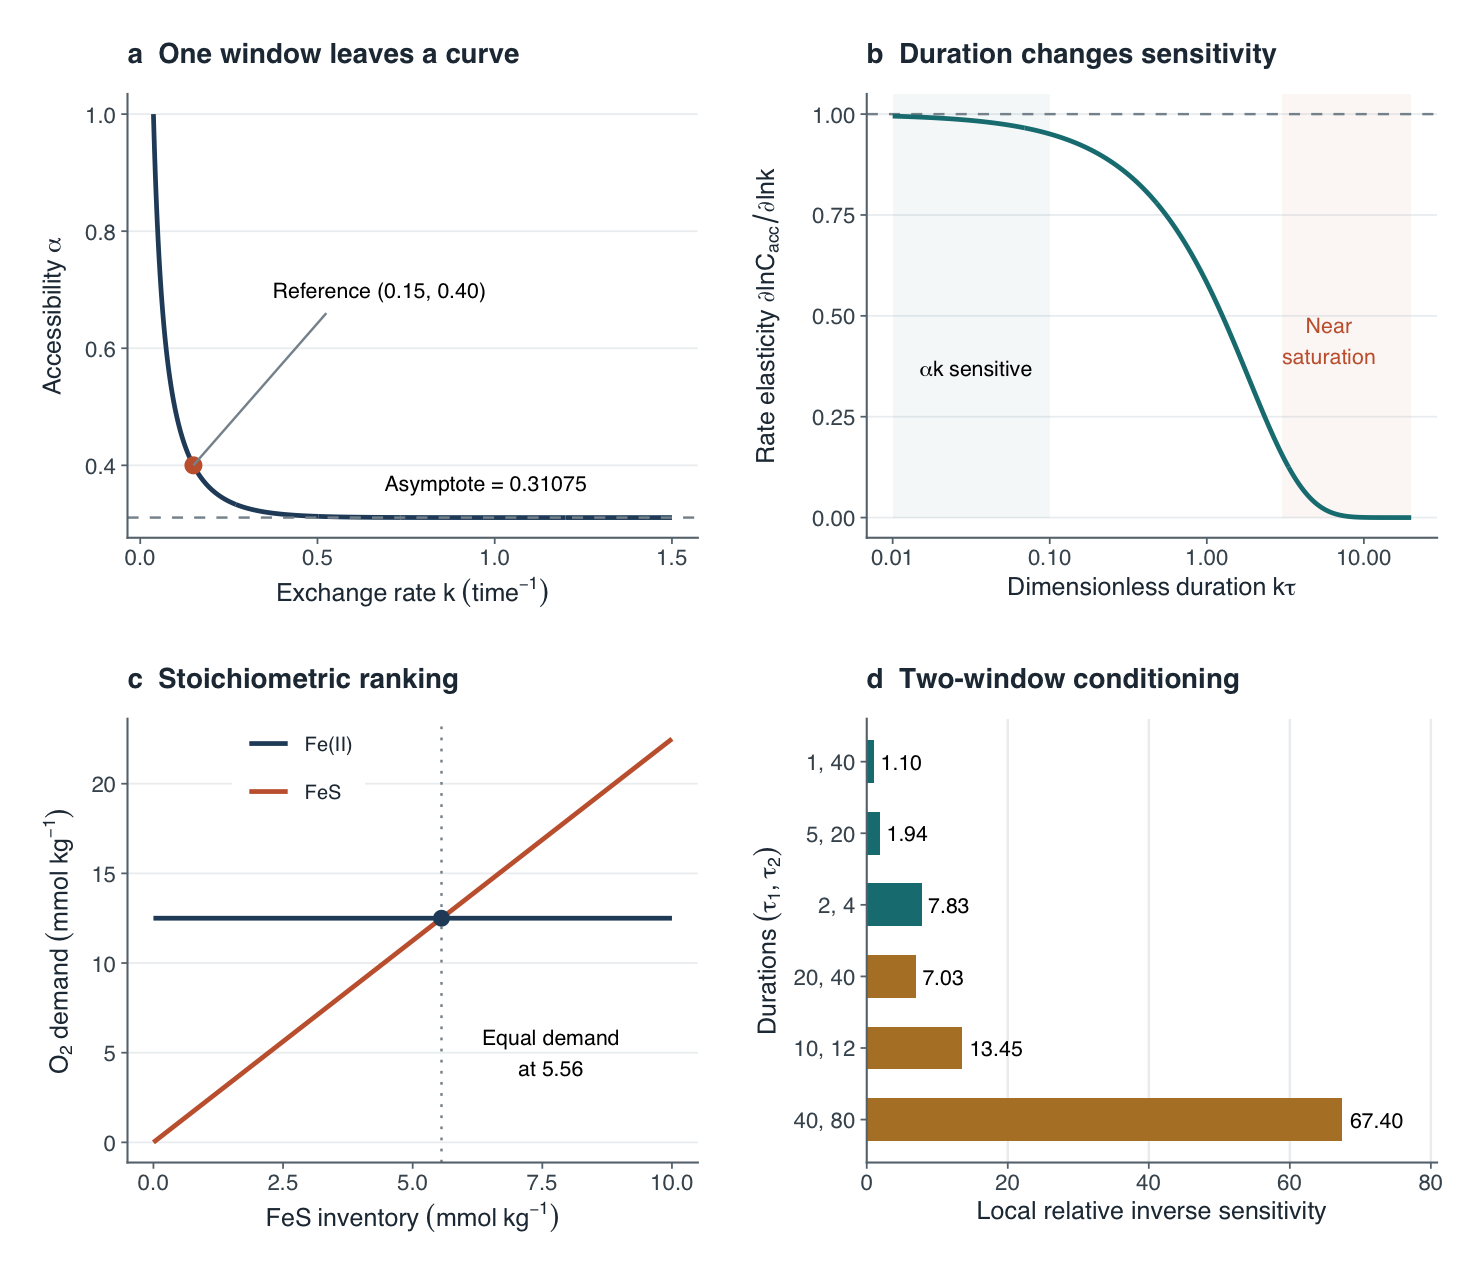
HRRI v1.0.9: Provides diagnostic functions for integrating longitudinal soil, plant and microbial observations during redox disturbance and recovery. Functions calculate stoichiometric potential oxygen demand, accessible electron capacity from explicitly supplied inventories and kinetic parameters, recovery signatures, fixed-reference domain scores, and exploratory multiblock scores with observation-coverage diagnostics. For background and methods see Sander, Hofstetter and Gorski (2015), Kluepfel et al. (2014), and Thompson et al. (2006). There are three vignettes including HRRI: Reading the Figures — A Worked Example and HRRI: Reproduce All Six Paper Figures in R.
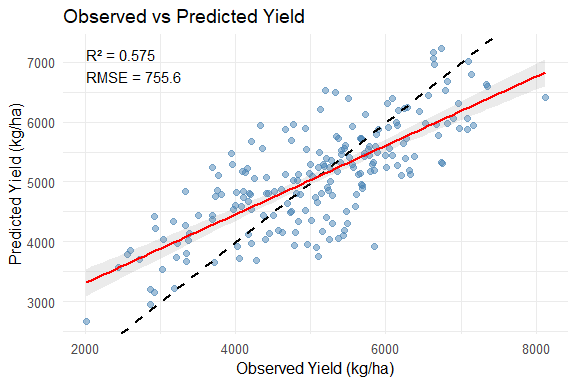
VeraCrop v0.1.0: Implements automated variable-type detection, preprocessing, encoding, scaling, model diagnostics, variable selection, and yield gap computation for agricultural comparative performance analysis. The comparative performance analysis approach is described in de Bie (2004). For an overview of yield gap assessment methodologies, see Kamkar et al. (2025). See the vignette to get started.
Causal Inference
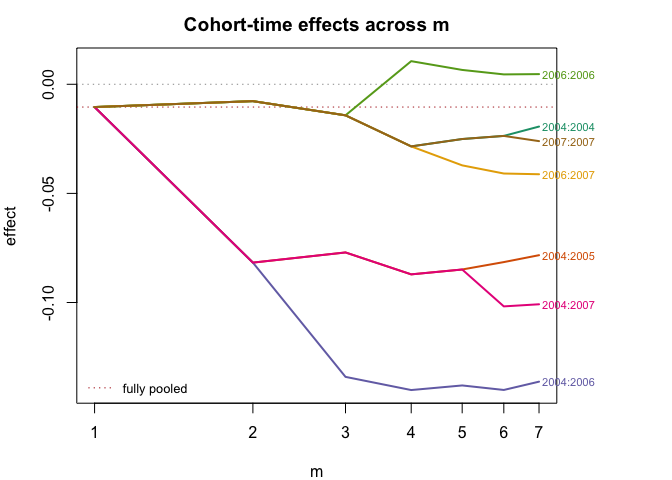
phdid v0.1.0: In staggered difference-in-differences designs the treatment effect is a vector of cohort-time effects. Estimating each separately is unbiased but imprecise when some are equal, while pooling them all is precise but biased under genuine heterogeneity. This package treats the choice as a partition-selection problem on the cohort-time cells and provides two estimators: a Dirichlet process mixture fitted by a collapsed Gibbs sampler and an L0-penalized estimator that returns a single partition. Methods are described in Arora and Wagle (2026). There are two vignettes Minimum wages and teen employment: recovering partial homogeneity and When partial homogeneity helps, and when it does not.
Climate Studies
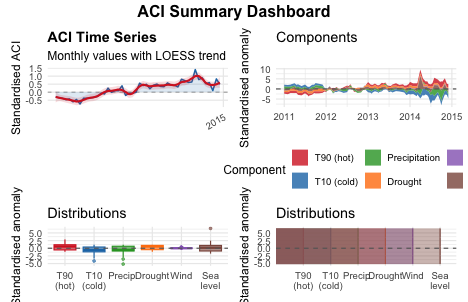
xaci v0.1.0: Computes the Actuarial Climate Index (ACI) and its components (temperature, precipitation, drought, wind, sea level) from gridded climate data (‘NetCDF’) and tide gauge records. Implements the methodology described in Garrido, Milhaud & Olympio (2025) for a French/European actuarial climate index, building on the American Academy of Actuaries framework, to any country in the world. There are seven vignettes including Get Started and Visualizing ACI Results.
Computational Methods
koopman.dmd v0.2.2: Implements Dynamic Mode Decomposition (DMD) with Koopman operator theory extensions, powered by a Rust backend via extendr; standard DMD as described in Schmid (2010), DMD with control for forced linear systems following Proctor, Brunton, and Kutz (2016); and Extended DMD with lifting functions, Hankel-DMD via time-delay embedding, Generalized Laplace Analysis for direct eigenfunction computation, and harmonic time averages and mesochronic harmonic plots for phase space analysis as developed in Mezic (2020). See the vignette.
RcppTrust v0.1.0: Implements functions for local optimization using derivatives and trust regions which are guaranteed to converge to a local minimum of the objective function. This is a thread-safe C++ port of the algorithm in the trust package exposed both as a drop-in R function and as a C-callable, thread-safe entry point in a manner so it can be used from parallel C++ code such as in nlmixr2est. See the vignette.
tulpa v 0.7.5: Provides a general-purpose engine for fitting Bayesian hierarchical models with spatial fields, temporal effects, spatially varying coefficients, and multiple inference backends. Scalable spatial structure includes Hilbert space approximate Gaussian processes (Riutort-Mayol et al. (2023)), nearest-neighbor Gaussian processes (Datta et al. (2016)), intrinsic conditional autoregressive models (Besag, York, and Mollie (1991)), the reparameterized Besag-York-Mollie model (Riebler et al. (2016)), and stochastic partial differential equation fields ( Lindgren, Rue, and Lindstrom (2011)). Temporal structure covers random walks, autoregressive processes, and Gaussian processes. Inference is tiered by correctness guarantee: exact Hamiltonian Monte Carlo with the No-U-Turn sampler, Laplace and nested Laplace approximations with hyperparameter integration (Rue, Martino, and Chopin (2009)), and variational inference. Model-specific packages plug observation likelihoods into the engine through a templated C++ callback interface. There are three vignettes including Getting started and Spatial Fields.
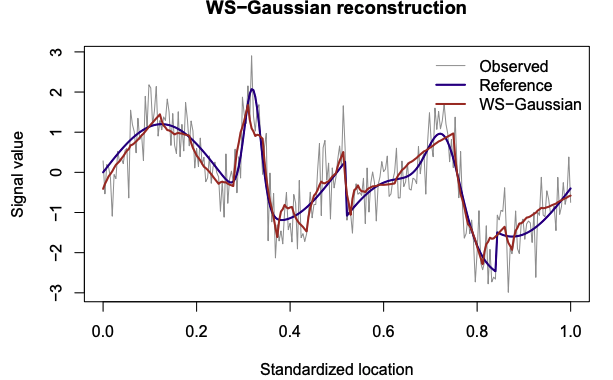
WSwavelet v0.1.0: Implements Bayesian wavelet denoising using a resolution-adaptive spike-and-slab prior whose continuous slab is a mixture of a compactly supported Wendland-type density and the semicircle density. Provides Gaussian and Laplace working-likelihood versions, empirical-Bayes fitting of resolution-specific slab weights, robust noise-scale estimation, posterior-mean coefficient shrinkage, reconstruction by the inverse discrete wavelet transform, and diagnostic tools. See the vignette.
Ecology
acousticTS v2.0.8: Acoustic target strength (TS) represents the intensity of an echo returning from an individual scatterer such as bubbles, fish, or zooplankton. TS can be used to convert integrated or volumetric backscatter collected from fisheries acoustic surveys into units of number density (e.g. animals per \(m^3\)), abundance (e.g. number of animals), and biomass (e.g. kg). This parameter can also be used to aid in classifying backscatter, such as separating likely echoes of large predatory fish (e.g. adult cod) from smaller prey (e.g. shrimp). Applications are described by Lucca et al. (2023), with fisheries-acoustics principles from Simmonds and MacLennan (2005). See the vignette.
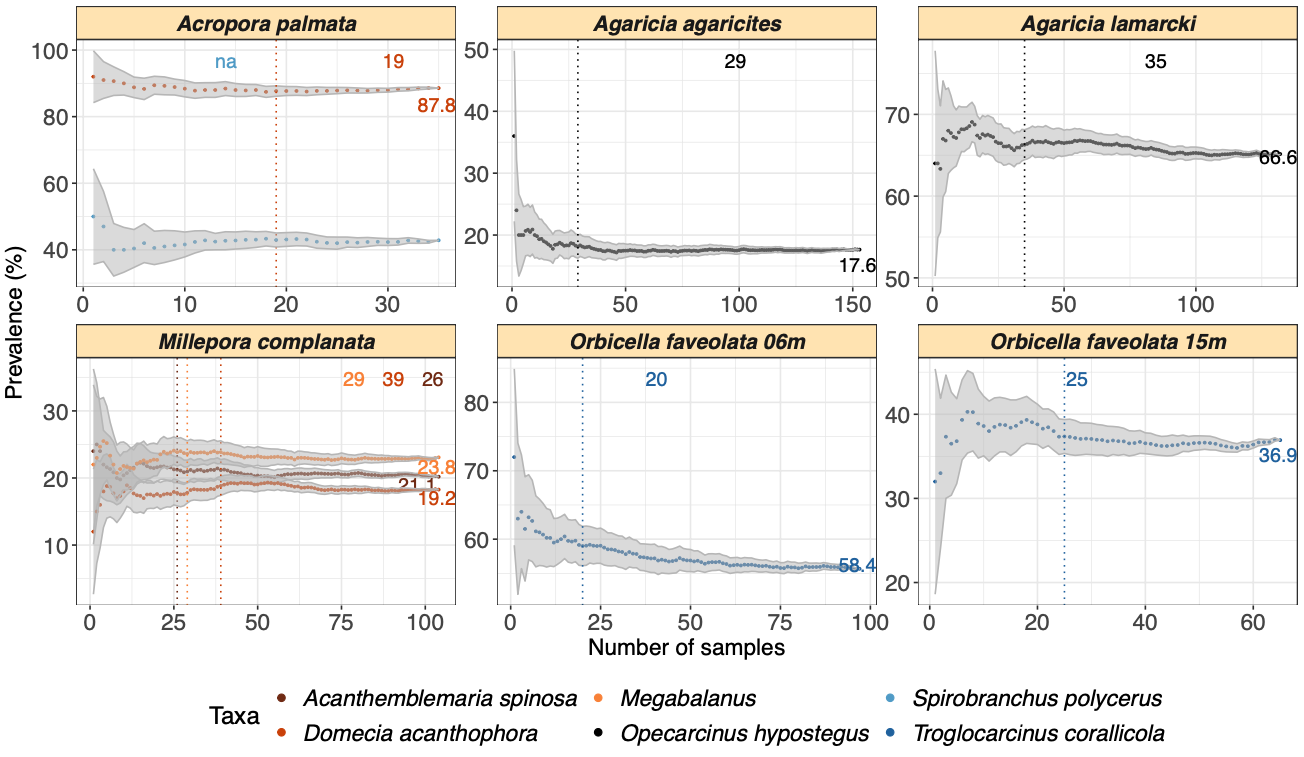
SAMPLE v1.0.1: Estimates the sampling effort needed to obtain stable species occurrence and prevalence rates from presence-absence data. The method repeatedly subsamples observations, evaluates changes in estimated rates, and reports the minimum stable sample size. For methodological details, see Bravo et al. (2025). Look here to get started.
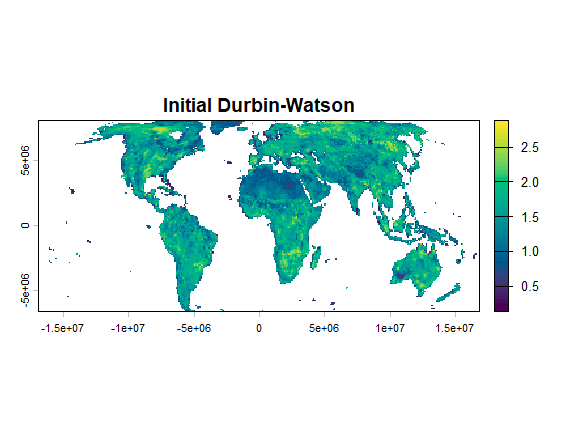
 sptrends 1.6.3: Provides a unified and reproducible framework for statistical inference of spatiotemporal trends in gridded environmental data that addresses the interconnected challenges of serial correlation, spatial dependence and multiple testing that commonly arise when analyzing gridded environmental time series. Core methods support serial-correlation treatment through trend-preserving prewhitening, pixel-wise and spatially explicit trend inference, slope estimation and multiple-testing correction. Dedicated workflows reproduce published methodologies, for example Gutiérrez-Hernández and García (2025) for True Significant Trends workflow and Gutiérrez-Hernández and García (2024) for Robust Trend Analysis workflow. Supporting utilities facilitate raster data import and inspection, anomaly calculation, spatial autocorrelation diagnostics, and more. There are six vignettes including: Dealing with serial correlation and Trend magnitude estimation.
Economics
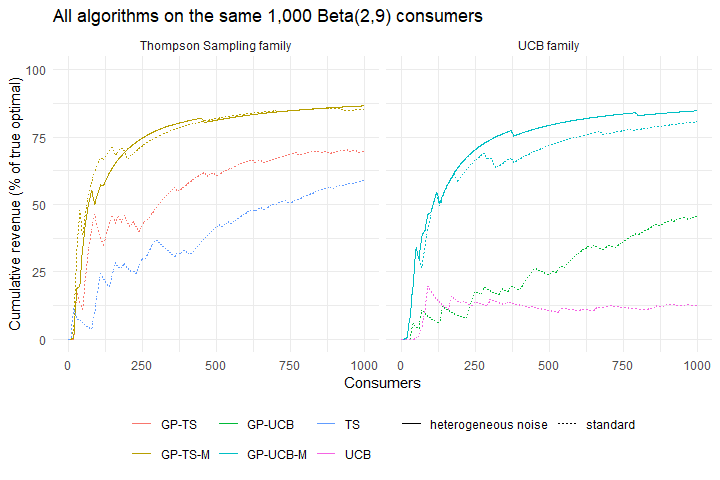
PricingBandits v2.1.0: Implements multi-armed bandit approaches for pricing experiments with an unknown demand curve, as developed in Weaver, Kumar, and Jain (2025). Includes Upper Confidence Bound and Thompson Sampling baselines, Gaussian process variants, monotonic Gaussian process variants that constrain demand to be weakly decreasing in price, and heterogeneous-noise extensions. The willingness-to-pay distribution is fully user-specified via a vector of consumer valuations, so any demand environment can be simulated or replayed. See the vignette.
Epidemiology
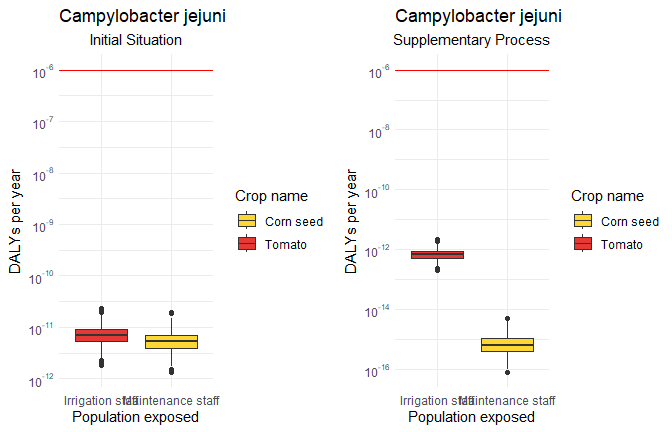
ambre v2.1.2: Provides a Quantitative Microbial Risk Assessment framework for the reuse of treated wastewater in agricultural irrigation. Following a multi-barrier approach, the package simulates pathogen inflow and removal along a treatment train, estimates human exposure, and computes health risk indicators such as infection probability, illness probability, and Disability-Adjusted Life Years. It also supports an economic analysis of the treatment scenarios considered. For more details see Thomas et al. (2024). There are eight vignettes including Get started and Interpreting risk against the WHO target.
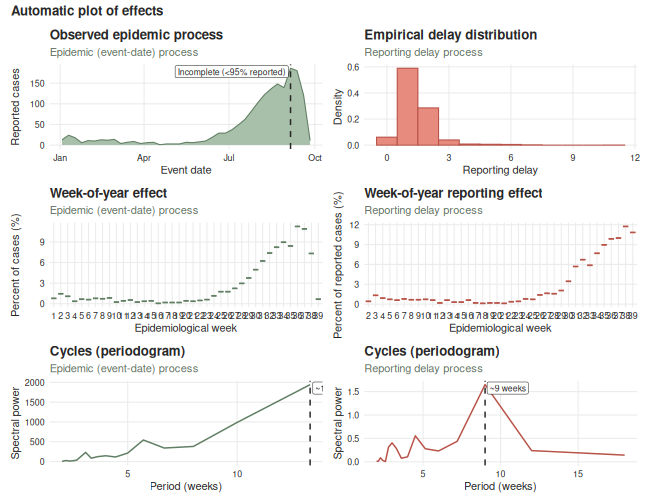
tbl.now v1.2.0: Defines tidy data structures and package-agnostic workflows for epidemiological nowcasting. The tbl_now class records event, report, and revision dates alongside strata, covariates tagged by model component, censoring, and reporting-delay metadata while remaining compatible with dplyr. Tools support validation, manipulation, diagnostics, visualization, format conversion, retrospective evaluation, and multiple modelling engines. See the vignette.
Genomics
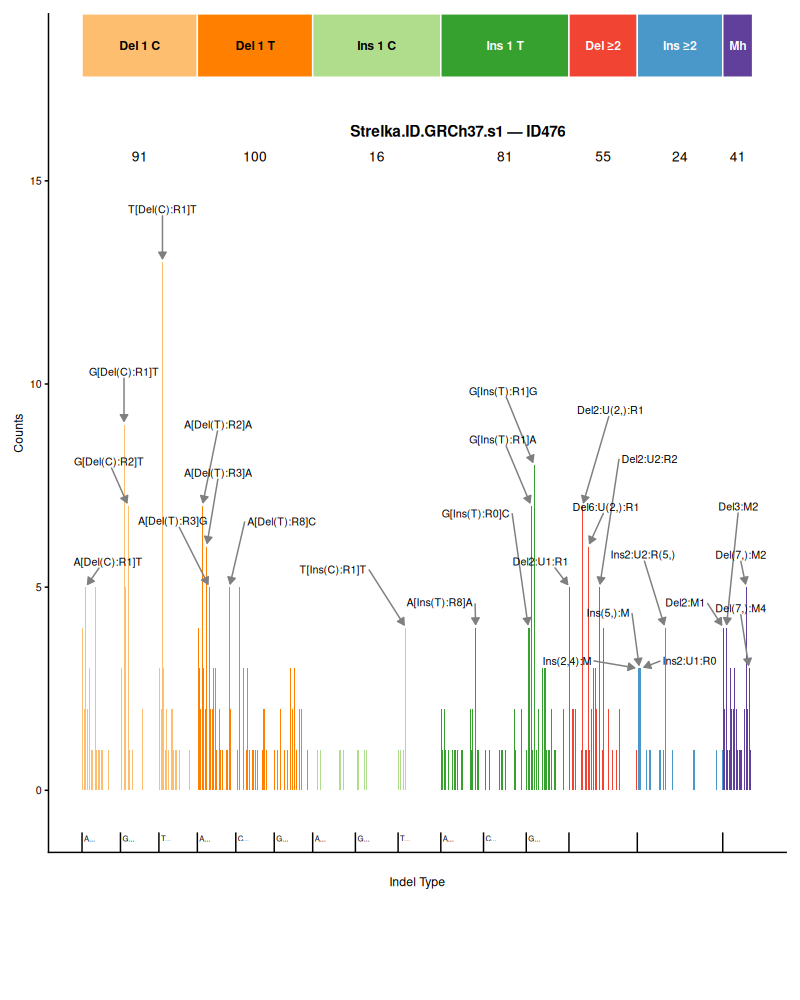
mSigSpectra v0.1.3: Reads variant call format (VCF) files in a caller-agnostic way, annotates variants with flanking sequence context and transcriptional strand, and builds mutational-spectrum catalogs of single base substitutions, doublet base substitutions, and small insertions and deletions at several resolutions (SBS96, SBS192, SBS1536, DBS78, DBS136, DBS144, ID83, ID89, ID166, ID476) and in both counts and density representations. Used in the preparation of Rozen et al. (2026). See the vignette.
Machine Learning
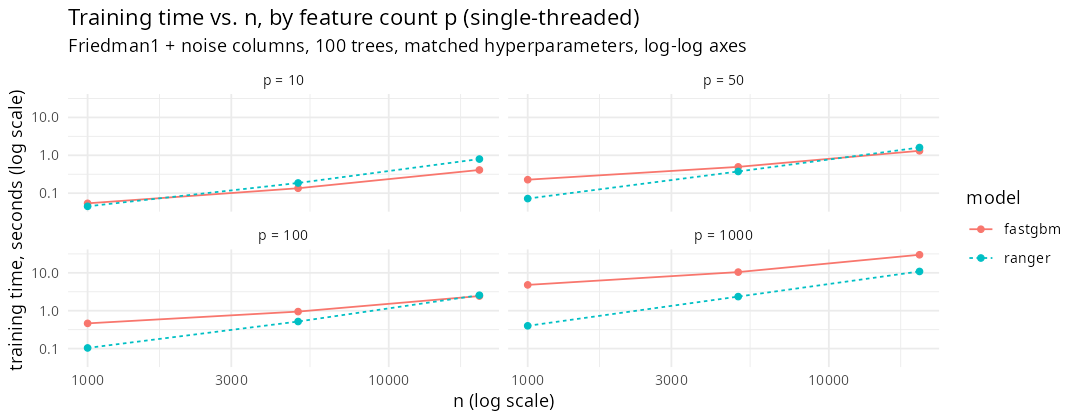
fastgbm v0.6.1: Implements a fast gradient boosting machine covering four task types with one interface: regression (squared error), binary and multiclass classification (logistic and one-vs-rest), and right-censored survival analysis via Cox (Breslow ties), accelerated failure time (normal location-scale), or piecewise-exponential objectives. Provides native missing-value routing, baseline-hazard estimation and survival-probability prediction for the survival objectives, and deterministic multi-threaded training via RcppParallel. Methods are described in Friedman (2001). There are six vignettes including getting Started and Algorithm.
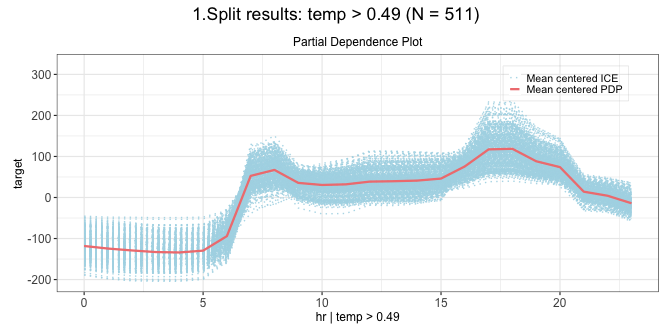
xplaineff v0.1.1: Implements the Generalized Additive Decomposition of Global EffecTs algorithm for interpretable machine learning. The package recursively partitions the feature space to minimize heterogeneity of feature effects (e.g., Accumulated Local Effects or Partial Dependence), producing a tree of regions where effects are more stable. It supports both ALE and PD strategies, works with mlr3 learners and provides visualization of the interaction tree and regional effect plots. The method is described in Herbinger et al. (2024). See the vignette.
Medical Statistics
chms v7.2: ActiGraph wGT3X-BT accelerometer processing methods using the standardized workflow developed by Statistics Canada for cycle 7 of the Canadian Health Measures Survey. The package promotes transparent and reproducible data processing while supporting the harmonization of analytical approaches among researchers wishing to align with Statistics Canada’s methods. For general details about the processing methods, please consult Clarke et al. (2026). See README to get started.
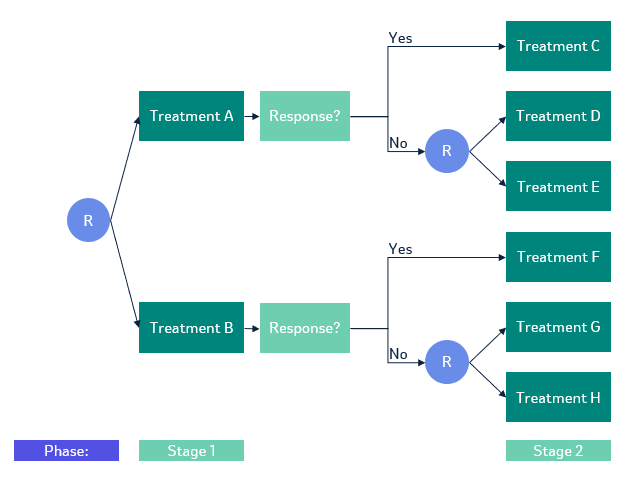
rsmart v0.1.0: Implements the interim augmented inverse probability weighted estimator for the value of treatment regimes embedded in sequential multiple assignment randomized trials. It subsumes both the inverse probability weighted estimator and the augmented inverse probability weighted estimator, enabling inference at interim and final analyses. Provides functions for value estimation, sandwich variance computation, group sequential stopping boundaries, and sample size determination for multi-stage SMARTs. See Manschot, Laber, and Davidian (2023) for additional details. There are four vignettes including Getting Started and Full demo of IAIPWE.
Meta-analysis
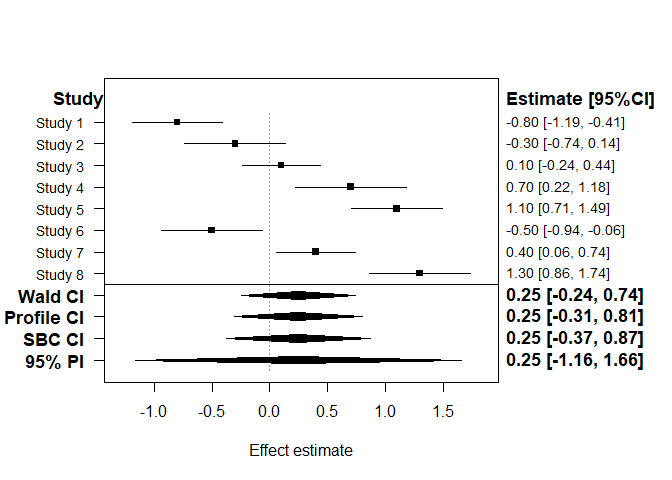
metaGLMM v1.0.0: Extends traditional random-effects meta-analysis by embedding it within a generalized linear mixed-effects model framework. The package supports covariate adjustment and non-normal responses using aggregate data, and provides likelihood-based inference with computationally efficient likelihood evaluation. The underlying methodology is described in Hanada and Sugimoto (2026). There are seven vignettes including Getting started and Prediction and forest plots.
Networks
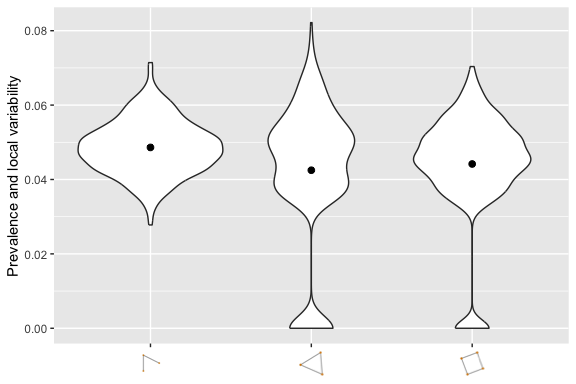
nethist v1.0.0: Estimates network histograms, a blockmodel approximation to the graphon underlying a network’s connectivity pattern, for both single-layer and multilayer networks. Implements graphon estimation methods including the profile-likelihood method of Olhede and Wolfe (2014) and the least-squares method of Gao, Lu, and Zhou (2015) for single-layer networks, and the multilayer extension of Song and Olhede (2026). See the vignette.
Phylogenetics
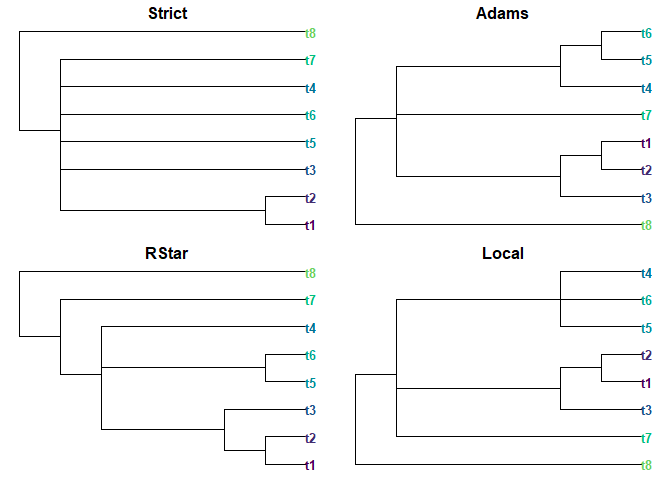
ConsTree v1.0.0: Efficient construction of phylogenetic consensus trees. Methods include strict, majority-rule, majority-rule (+), loose (combinable component, semi-strict), greedy, Adams, frequency difference, R*, and local consensus. See the vignette.
Statistics
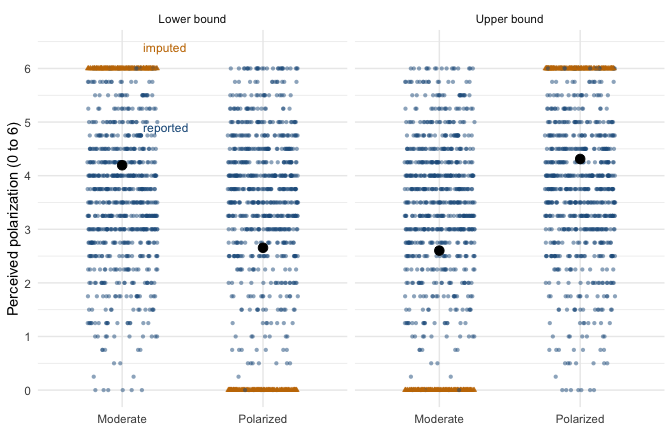
attrition v1.0.0: Implements the double-sampling bounds estimator of Coppock et al.(2017) for randomized experiments with nonignorable missing outcomes. Provides worst-case (Manski) bounds, double-sampling bounds with analytic variance and Imbens-Manski confidence intervals, Lee (2009) trimming bounds with analytic and bootstrap standard errors, covariate adjustment via poststratification, and a sensitivity analysis for violations of the outcome stability assumption. See the vignette.
FitVerse v1.0-2: Provides a unified interface for fitting parametric probability distributions to continuous univariate data that supports fifty-two distribution families spanning symmetric, right-skewed, heavy-tailed, bounded, and extreme-value shapes distributions, and three estimation methods. Automatic best-fit selection is performed using multiple criteria and tests. Includes publication-quality diagnostic plot, histogram overlaid with density curves and optional interactive plots via plotly. Additional tools include bootstrap confidence intervals for parameter estimates and return levels, batch fitting across multiple columns and more. Functions support data characterization in survey sampling, hydrology, and actuarial workflows. See Hosking (1990) for background and the vignette for examples.

hdcce v0.1.0: Estimation and inference for panel data models with interactive fixed effects. The methods cover the linear specification of Ruecker, Vogt, Linton, and Walsh (2025), and the dictionary design of Ruecker, Vogt, and Linton (2026). See the vignette.
HDElliptical v0.1.3: Provides fast, documented implementations of robust estimation, testing, dimension reduction, classification, and clustering methods for high-dimensional elliptically symmetric data. Computational kernels use Rcpp and RcppArmadillo. The package follows methods reviewed in Feng (2026). See the vignettes Robust Directional Foundations and Location Tests.
iop v0.1.0: Provides estimation, inference, and quantities of interest for ordered probit and ordered logit models whose outcome contains an inflated category: a single ordered category that mixes observations generated by the ordered process with observations generated by a distinct split-population process. Fits the zero-inflated ordered probit of Harris and Zhao (2007) and its middle- and top-inflated extensions (See for example Bagozzi, Joo and Mukherjee (2024)). Also provides analytic, robust, and cluster-robust standard errors, survey weights and offsets, model comparison, regime-specific predicted probabilities and first differences and additional features. There are four vignettes including Getting started and The model, identification, and estimation.
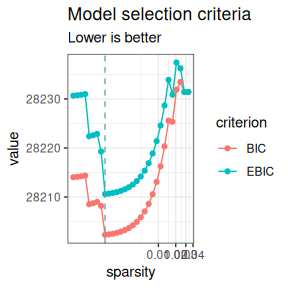
normalblockr v0.3.0: Implements the Normal-Block model, a Gaussian graphical model with a latent clustering structure for the multivariate analysis of continuous data that clusters variables and, building on the graphical lasso, infers a network of statistical dependencies between clusters rather than between individual variables, for known or unknown clusterings, with an optional zero-inflation extension for data with an excess of exact zeros. See Tous & Chiquet (2026) for the model itself and its variational expectation-maximization estimation procedure. There are four vignettes including Mean-Block models and Zero-inflated Normal-Block models.
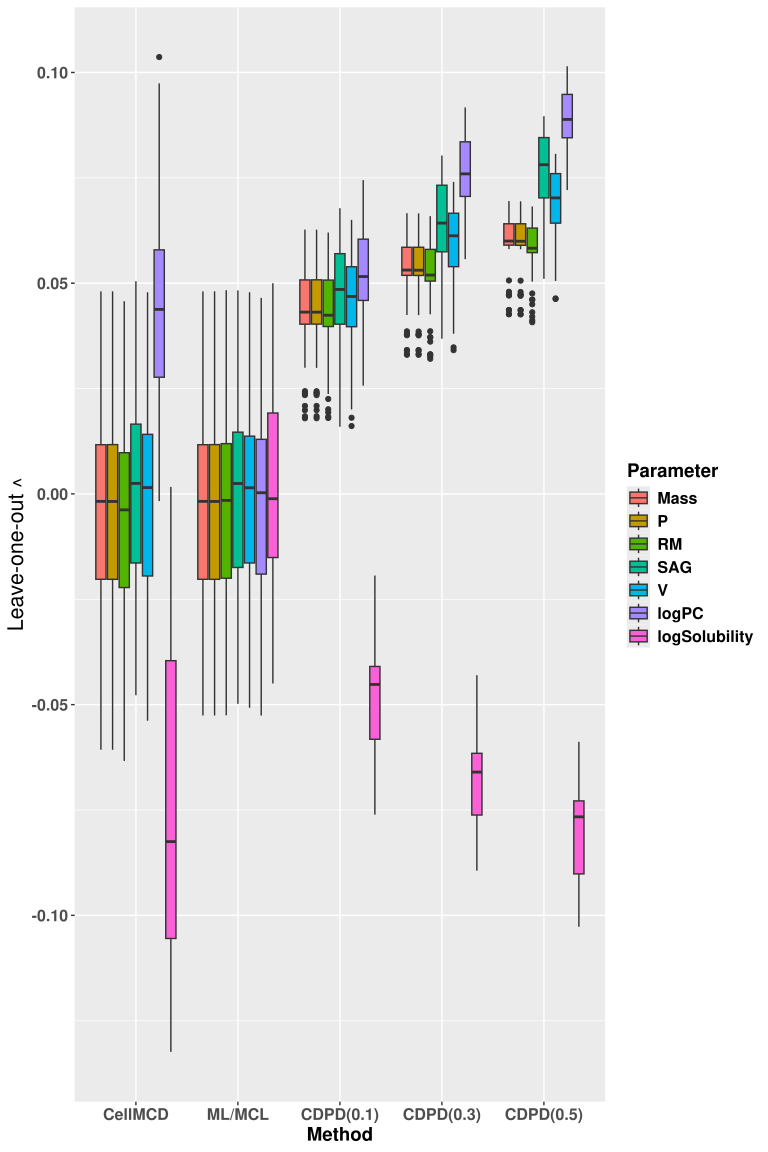
mvdpd v0.1-1: Provides robust multivariate estimation based on multivariate, composite and componentwise Density Power Divergence minimization in multivariate normal distribution for casewise and cellwise contamination and robust estimation for multivariate ordered gamma model using multivariate and composite DPD minimization. See Ghosh, Agostinelli, and Basu (2026) for details) and the vignettes mvnormDPD examples and mvogammaDPD examples.
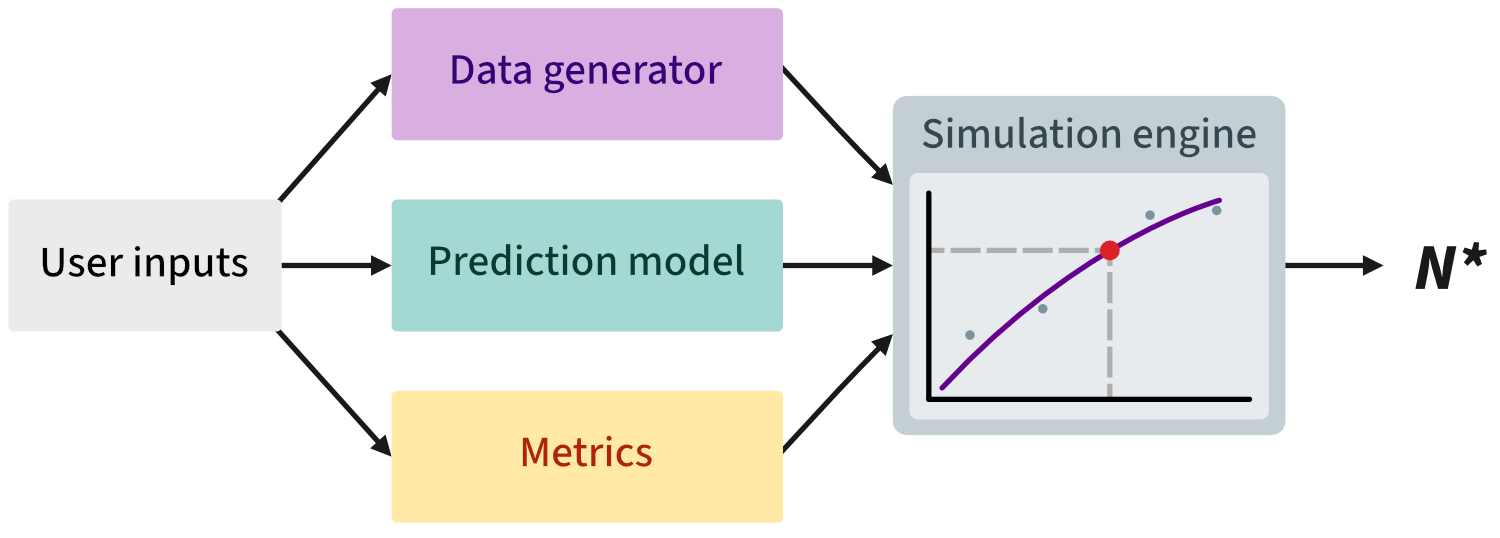
pmsims v1.0.0: Provides a flexible, simulation-based toolkit for exploring how much data are needed to develop reliable prediction models. It works by repeatedly generating data, fitting models, and evaluating performance to show how sample size affects predictive accuracy, calibration, and overfitting. The package supports continuous, binary, and time-to-event outcomes and can be used with both regression-based modelling approaches and machine-learning methods. Methods are described in Olaniran et al. (2026) and Shamsutdinova et al. (2026). See the vignette.
spfcICOMP v0.1.0: Implements shrinkage principal fitted components for sufficient dimension reduction in high-dimensional regression and classification. Provides regularized covariance estimation using Oracle Approximating Shrinkage and Maximum Entropy Covariance, structural-dimension selection using conventional and information-complexity criteria, response-guided feature screening, reduced-space prediction, and simulation utilities. Methodological foundations include Cook and Forzani (2008), Chen et al. (2010), Bozdogan (2000), and Olorede and Yahya (2019). See the vignette.
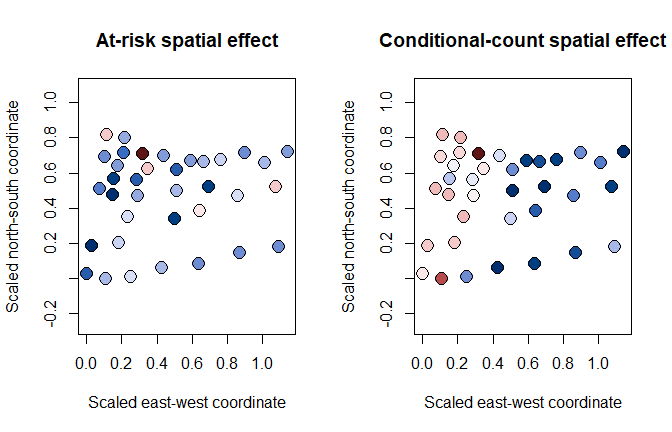
ZINB.GP v1.0.0: Fits Bayesian zero-inflated negative binomial regression models with Gaussian process random effects for spatial, temporal, or spatiotemporal count data. Provides Markov chain Monte Carlo sampling, configurable random effects in the zero-inflation and count components, and posterior predictive draws. Implements a full GP version of the methods described by He and Huang (2024). See the vignettes Oregon Landslides and Simulating and Fitting a Spatiotemporal ZINB-GP Model.
Surveys
risq v3.0.1: Calculate representativity indicators for survey quality based on survey data and response models. Use partial indicators to analyse the impact of individual variables and categories. Monitor changes in representativity during data collection. Improve representativity through adaptive survey design. Supports both R-indicators and coefficients of variation. See Schouten, Cobben, Bethlehem (2009), Shlomo, Skinner, Schouten (2012) and Schouten, Shlomo (2017). There are two vignettes: Introduction and Theory.
Utilities
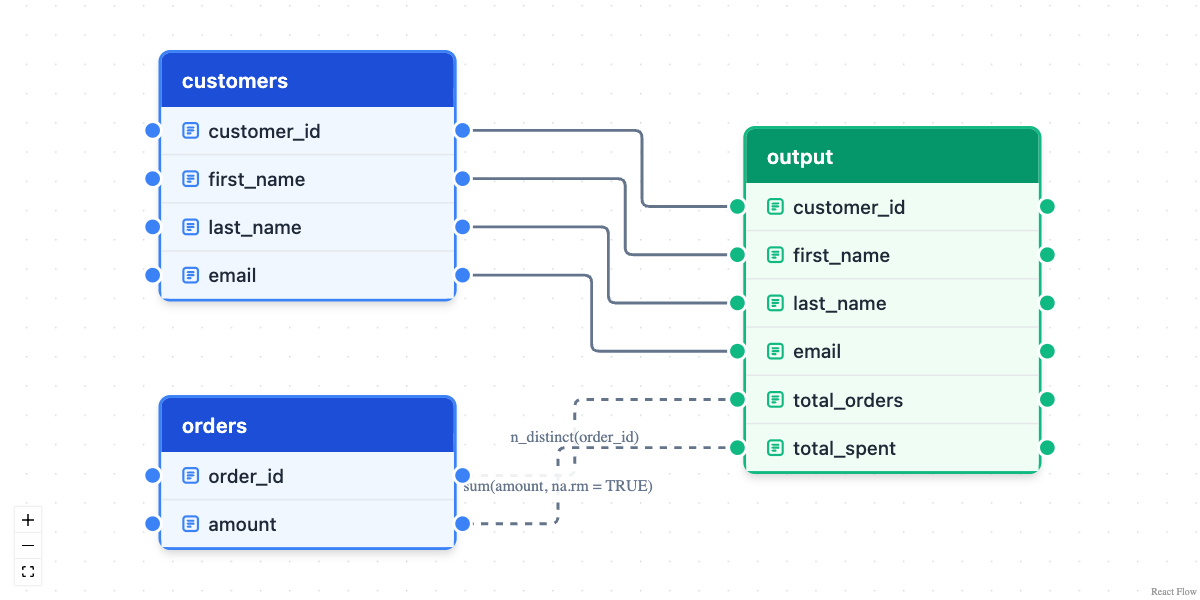
dplyneage v0.3.1: Implements column lineage visualizations using React Flow for'dplyr and dbplyr pipelines. Provides a tidyverse-style interface for tracking data transformations through pipeline operations. There are two vignettes including Getting Started with dplyneage and Building the React Flow Bundle.
ducklake v0.6.0: A tidyverse-friendly interface to DuckLake, the DuckDB lakehouse format. Attach versioned data lakes from R and work with them using familiar dplyr verbs, with support for ACID transactions, time travel queries, snapshot audit trails, data inlining, encrypted storage, multiple catalog backends (DuckDB, PostgreSQL, SQLite, MySQL), and remote access over the ‘Quack’ protocol from DuckDB. There are nine vignettes including ducklake Cookbook and Time Travel Queries.
getaca v0.1.6: Provides functions to declare, retrieve, verify, track and actively manage external data dependencies too large or too fast-moving to ship inside a package. Resources are identified by package, name and version, pinned to a Secure Hash Algorithm (SHA-256) checksum, and resolved through an explicit policy so that the same installed package always resolves the same bytes. A registry served from a remote host may be signed with Ed25519 and verified against a key the declaring package ships, so the declaration and the key that vouches for it arrive by different routes. Designed for reproducible offline use and graceful behavior during package checks. There are eight vignettes including Quick Start and Policies and Channels.
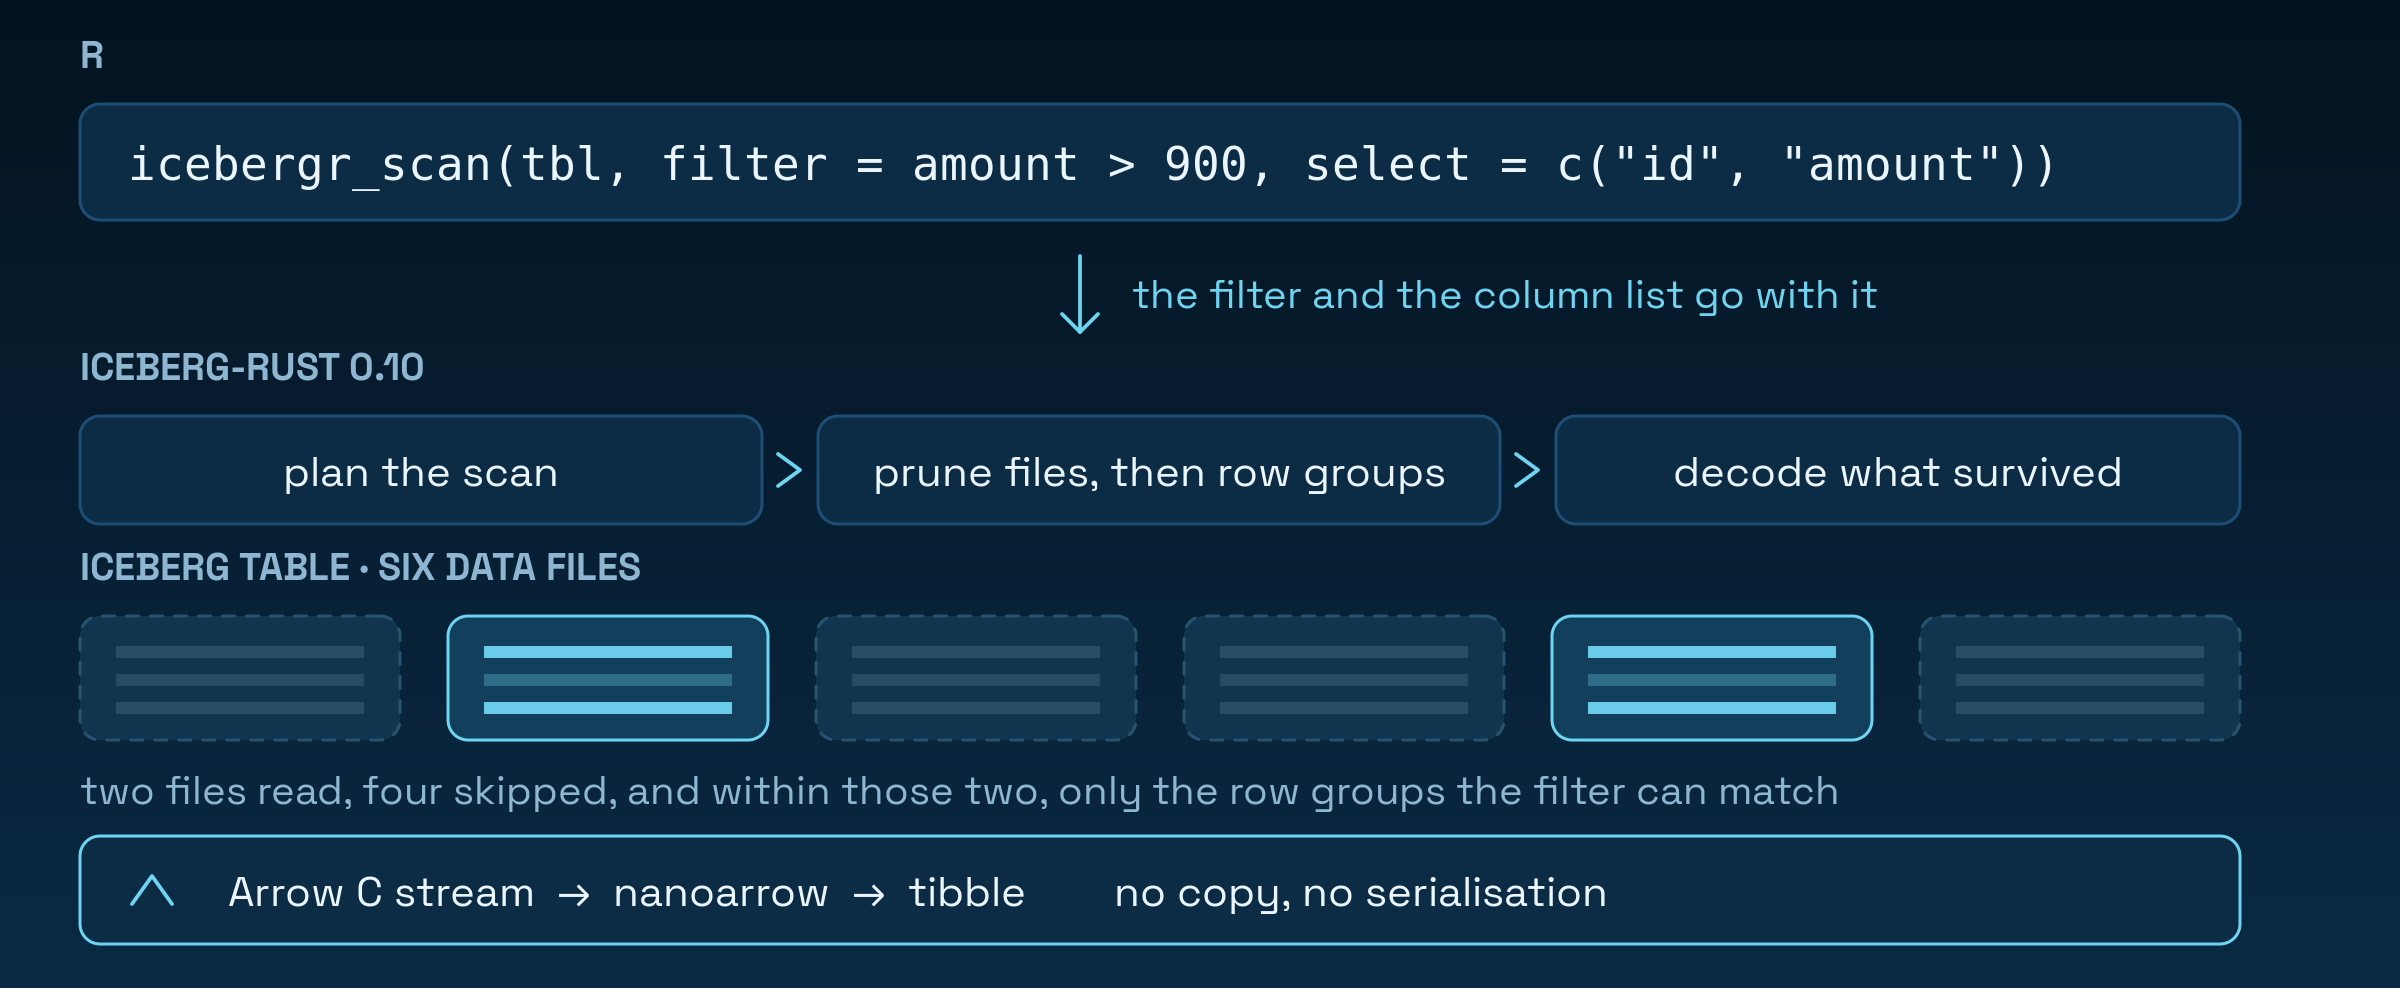
icebergr v0.2.0: Implements a native client for Apache Iceberg, the open table format used by Snowflake, Databricks, BigQuery, AWS and Dremio that connects to REST and AWS Glue catalogs, lists namespaces and tables, reads the schema and partition specification of a table, scans data with predicates and projections pushed down, travels back through snapshot history, and appends new data. Apache Arrow is the interchange layer throughout. See the README for the full matrix of supported and unsupported features. There are seven vignettes including Getting Started and What Iceberg Is, and What It Fixes.
pkgcheck v0.3.4: Check whether a package is ready for submission to the rOpenSci peer review system. Incorporates the goodpractice package and many additional checks, including aspects related to maintenance of online public code repositories. There are four vignettes including Current checks and Adding or modifying checks.
Visualization
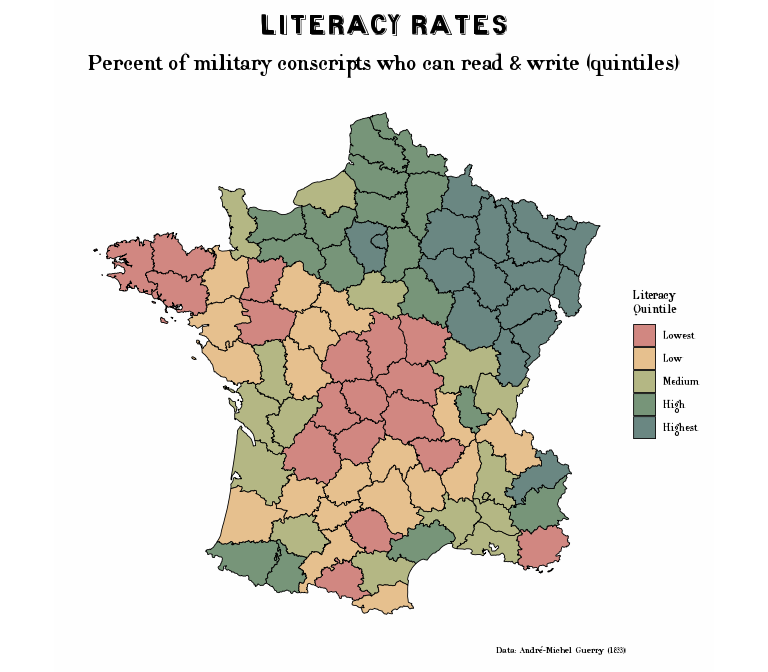
ggCheysson v1.1.0: Implements for ggplot2 the stylistic elements (fonts, hatched patterns, color palettes) used by Emile Cheysson in the Albums de Statistique Graphique, sometimes called the pinnacle of the Golden Age of Statistical Graphics. There are three vignettes including Getting Started and Mapping Guerry’s Moral Statistics with Cheysson Palettes.
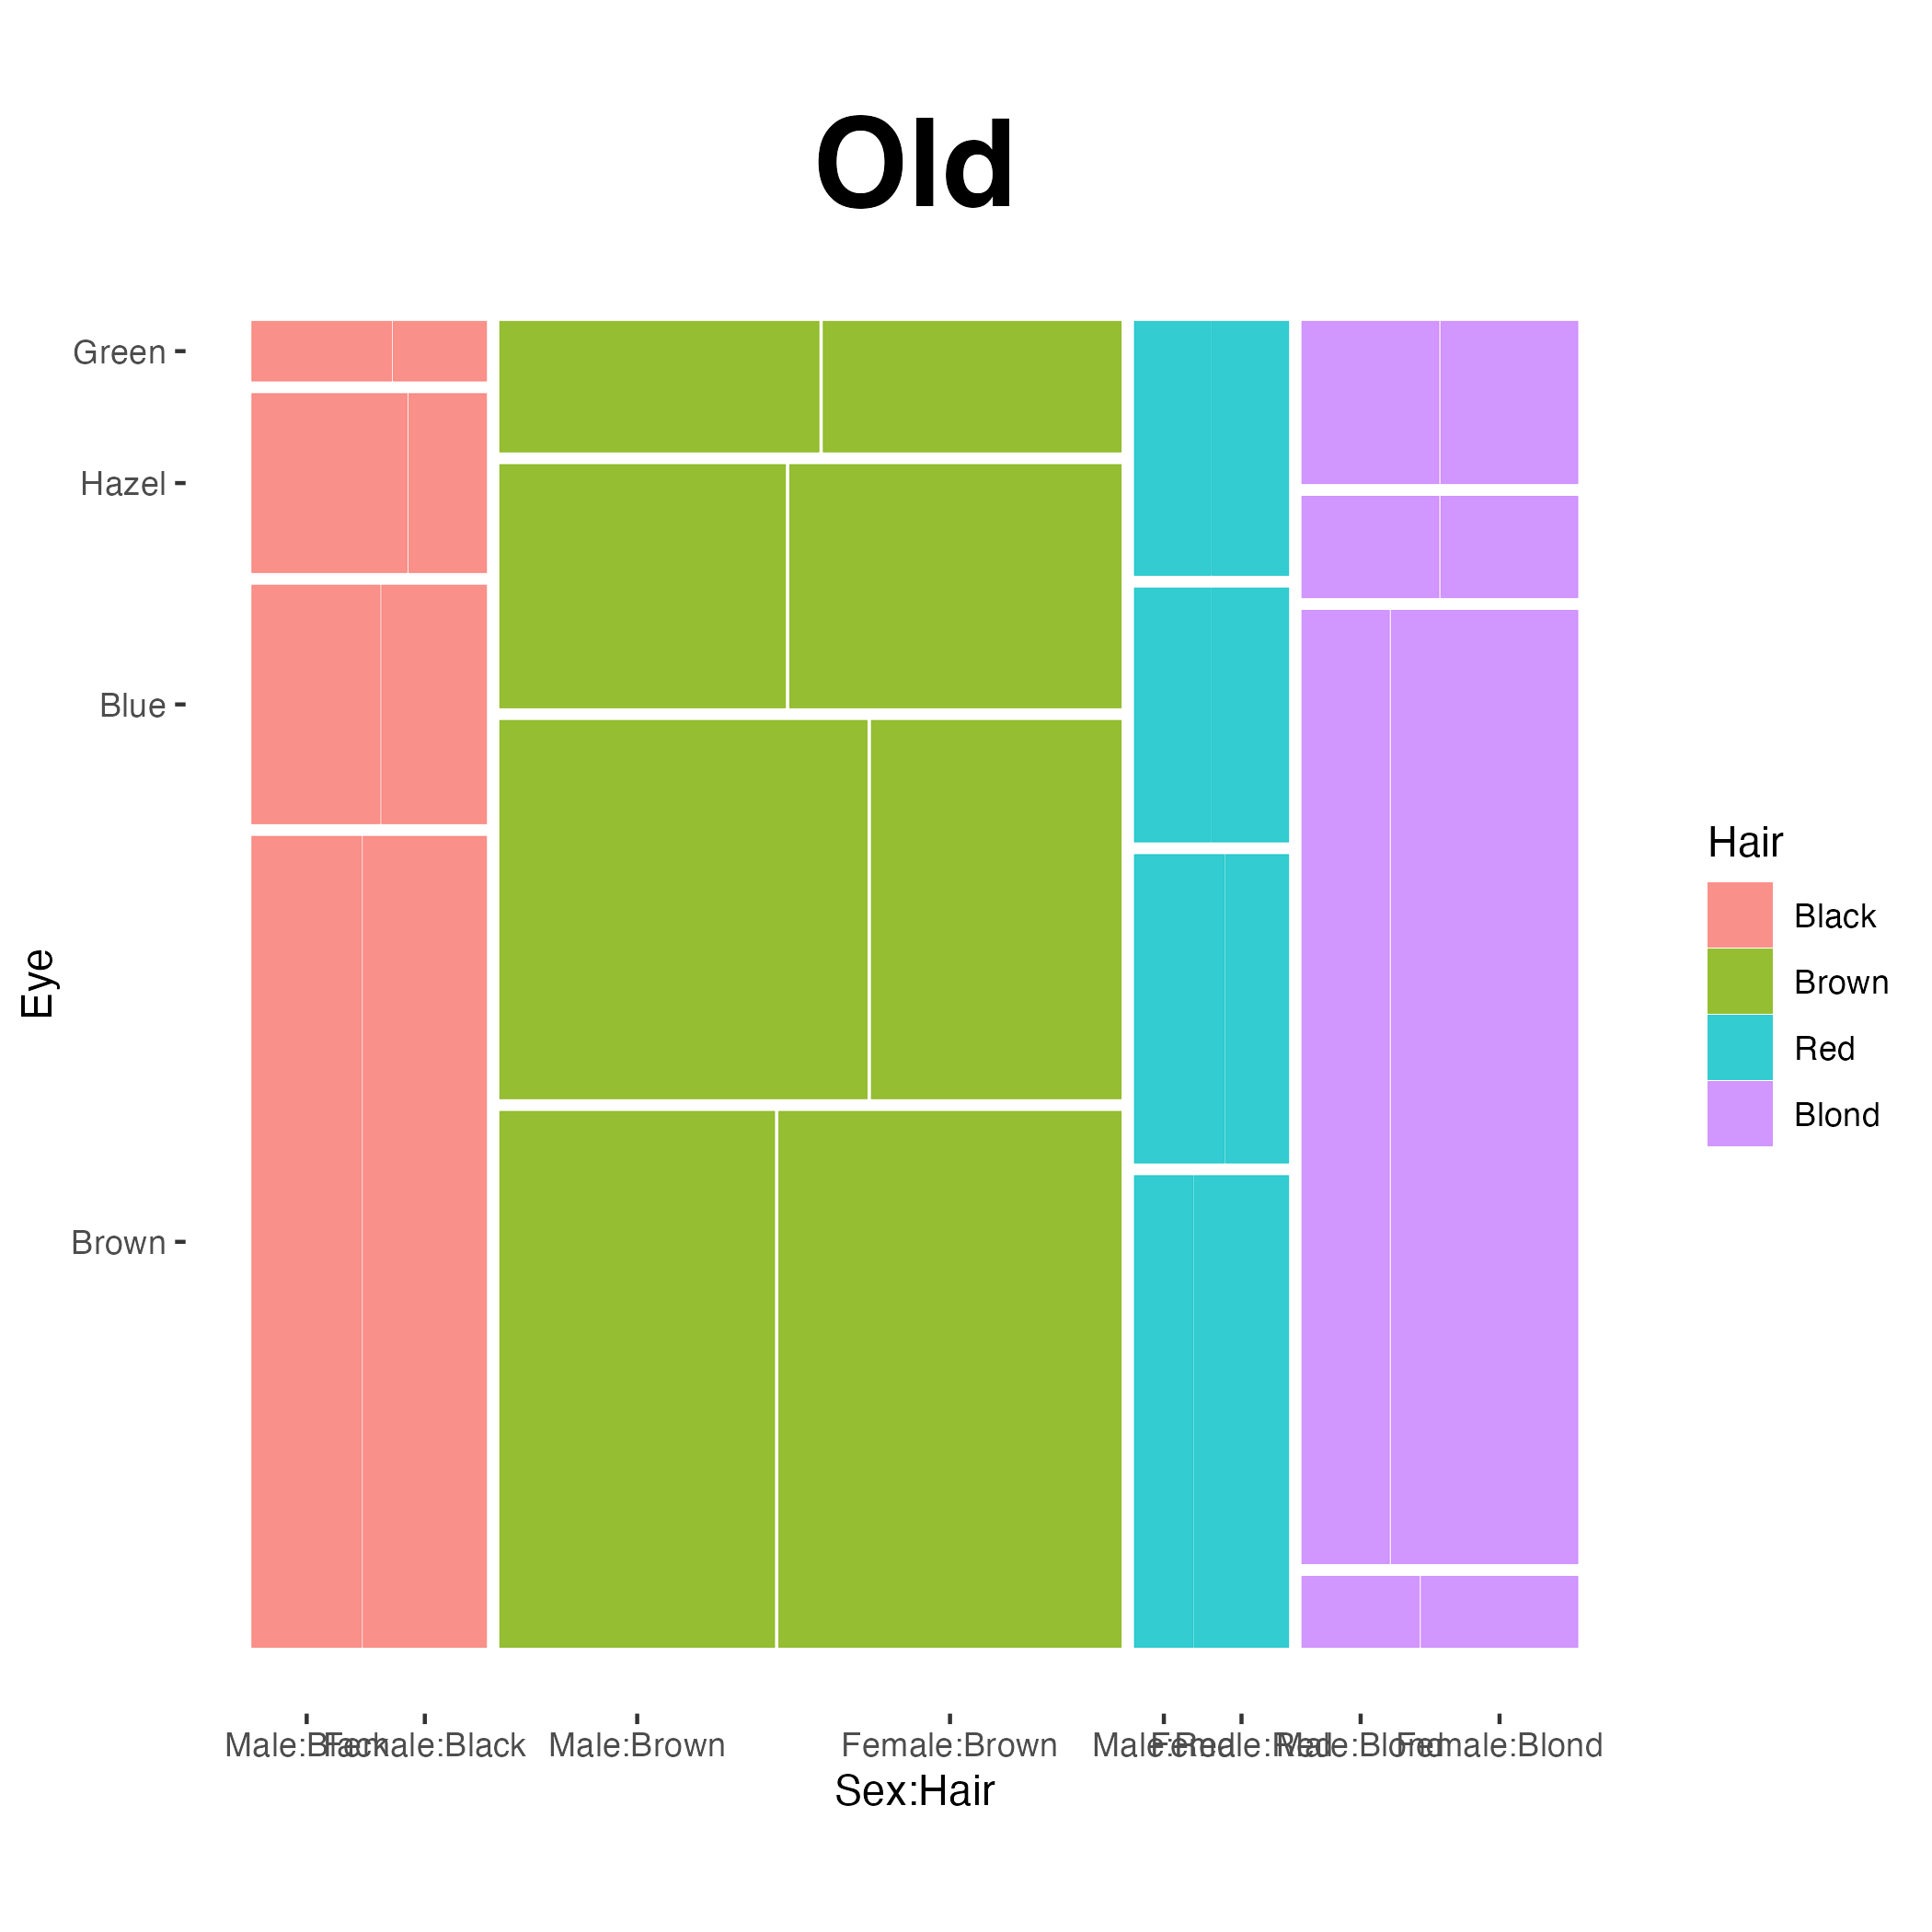
ggmosaic2 v0.5.1: Extends ggplot2 framework by providing the geom geom_mosaic. Allows fitted loglinear models which can be used to show patterns of association among variables in frequency tables. There are four vignettes including Introducing ggmosaic2 and Three Forms of Frequency Tables.